AI Evaluation

Systematically improve your AI quality

Run offline and online evals to measure agent performance. Catch quality issues before they reach users and iterate with confidence using LangSmith's comprehensive evaluation framework.

Try LangSmith free. No credit card required.

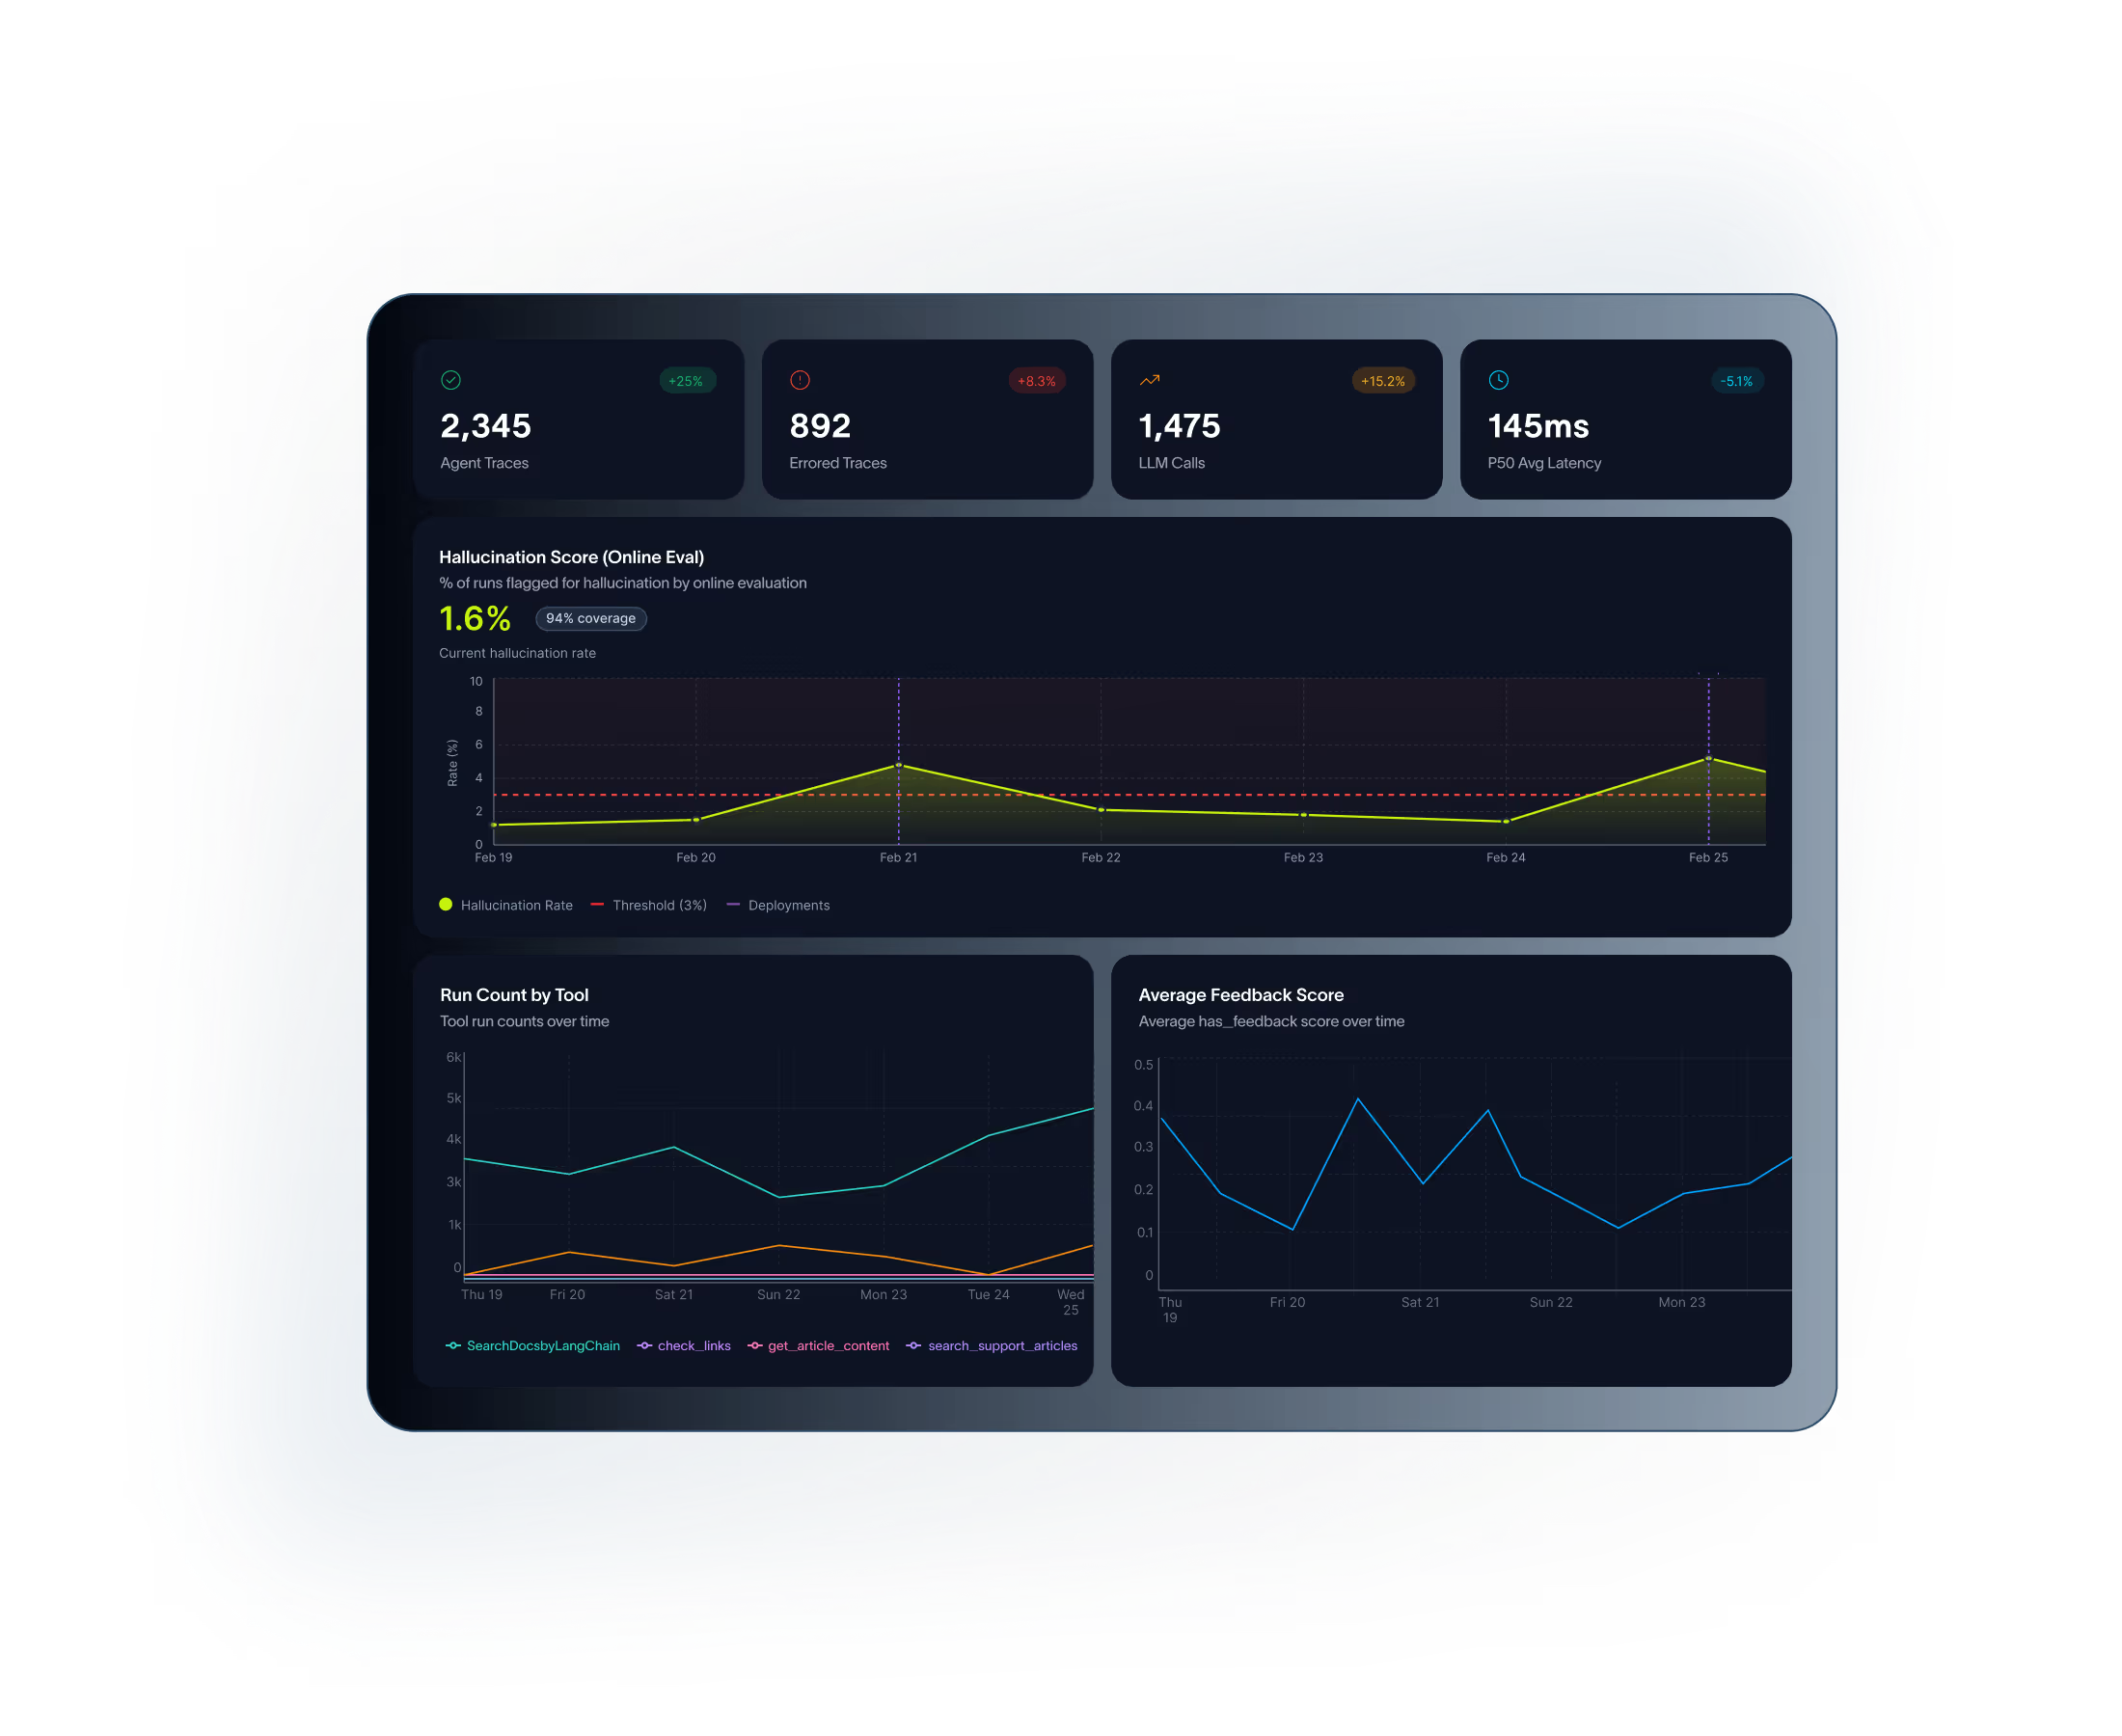
LangSmith Observability dashboard showing agent traces, evaluation scores, latency, and feedback trends

LangSmith powers top engineering teams, from AI startups to global enterprises

Zip
Writer
Harvey
Vanta
Abridge
Clay
Rippling
Mercor
Listen Labs
dbt Labs
Klarna
Headspace
Lyft
Coinbase
Rakuten
LinkedIn
Elastic
Workday
Monday.com

Powering the AI Evaluation Lifecycle

Turn production traces into repeatable evaluations that connect testing, deployment, monitoring, and continuous agent improvement.

LangSmith Engine at the center of the agent development lifecycleAgent development lifecycle ringBuild stage with Deep Agents, LangChain, LangGraph, and LangSmith FleetTest stage with datasets, evaluations, and experimentsMonitor stage with tracing, dashboards, online evaluations, and user feedbackDeploy stage with runtime, agent server, sandboxes, and context hubGovern stage with LLM Gateway

Trusted by Leading AI Teams

Teams rely on LangSmith evaluations to measure and improve AI quality at scale

50M+
LLM Calls Traced
1B+
Events Ingested per Day
100K+
Monthly active orgs in LangSmith SaaS

LangSmith Agent Engineering Platform

Observe, evaluate, and deploy agents with LangSmith. LangSmith is framework-agnostic: trace your preferred framework or integrate LangSmith with any agent stack using our Python, TypeScript, Go, or Java SDKs.

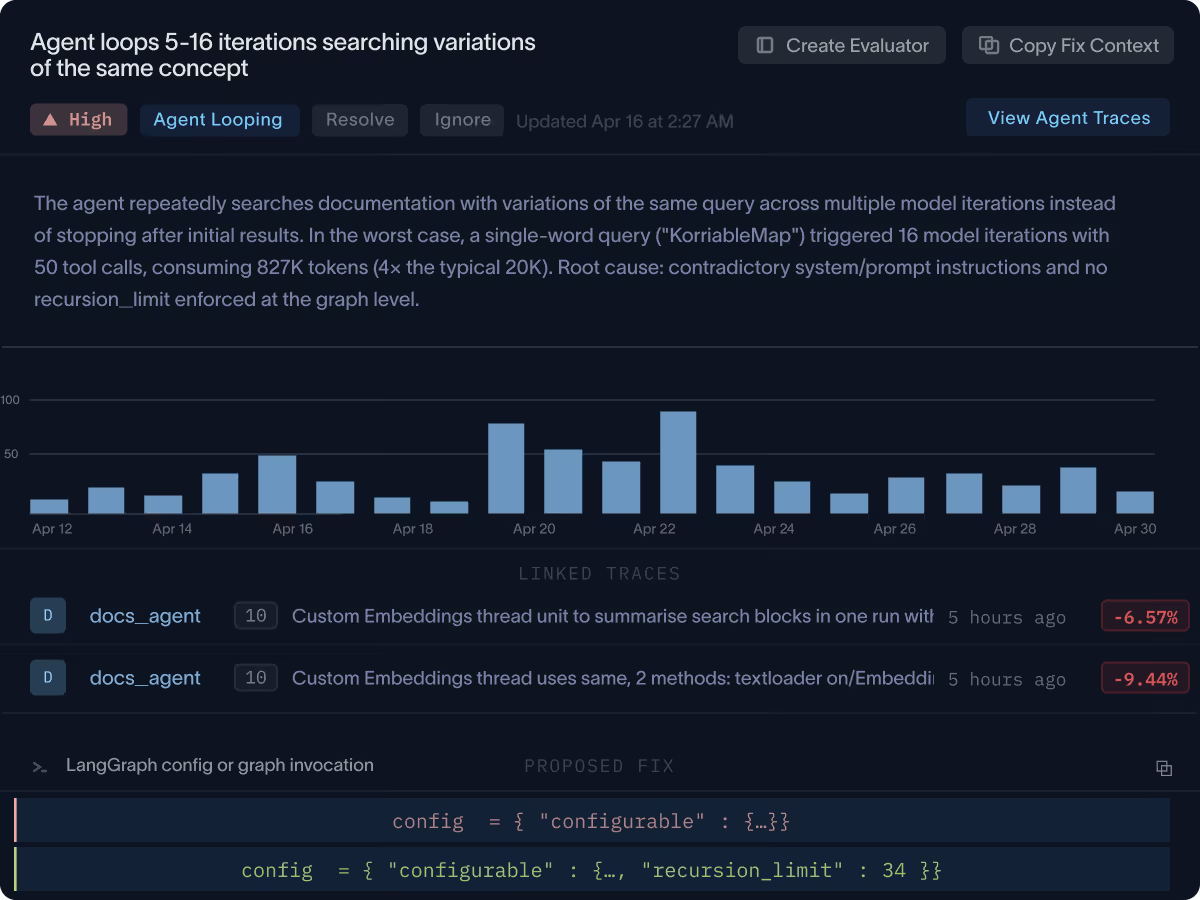
Surface and diagnose undetected issues autonomously to improve agents faster. LangSmith Engine clusters production failures into prioritized issues, finds the root cause in your traces and code, and proposes the fix for your review.

Read the announcement
LangSmith Engine issue analysis and proposed fix interface

How LangSmith AI evaluation works

1

Create evaluation datasets

Build eval datasets from production traces or manual examples. LangSmith makes it easy to curate representative test cases.

2

Run automated and LLM-based evals

Execute evaluations with custom metrics, semantic similarity scorers, and LLM-as-judge evaluation. Get instant feedback on quality.

3

Measure improvements and deploy

Compare eval results across experiments. Ship improvements with confidence knowing they're backed by rigorous evaluation data.

Built for Enterprise

Security and compliance at scale

LangSmith meets the demanding security, performance, and collaboration requirements of large organizations building AI applications at scale.

Permissions icon

Granular permissions

Role-based access control with org-level permissions and project isolation to meet your security and compliance requirements.

Security certification icon

SOC 2 Type II

Third-party security certification with comprehensive security controls.

Trust center
Deployment icon

Self-hosted deployment

Self-hosting options to maintain full control over your AI data and meet strict compliance requirements.

Meet us at an upcoming event

Join the LangChain community at conferences, meetups, and webinars to learn how teams are advancing ai evaluation in production.

See all events

Customers

Elastic

"Working with LangSmith on the Elastic AI Assistant had a significant positive impact on the overall pace and quality of our development and shipping experience. We couldn't have delivered the product experience our customers now have without LangSmith—and we couldn't have done it at the same pace without it."

James Spiteri, Director of Security Product Management at Elastic

Read case study
Rakuten

"What we really needed was a more structured way to test new approaches, something better than just shipping and seeing what happened. LangSmith gave us a more scientific, structured way to understand what was actually working, whether that meant running pairwise evaluations or digging into why accuracy jumped from 70% to 80%. Our engineers especially love the intuitive debugging experience, it's saved us a lot of time."

Yusuke Kaji, General Manager of AI for Business Development at Rakuten

Read case study

Get a Demo of LangSmith for AI Evaluation

See how LangSmith's evaluation framework helps teams systematically measure and improve AI quality.